Attention-guided Fine-tuning of Multimodal Large Language Models Improves Chain-of-Thought Reasoning
Sanchit Sinha, Guangzhi Xiong, 刘博涵 (Bohan Liu), Zhenghao He, Aidong Zhang
摘要
此摘要由英文原文自動翻譯。
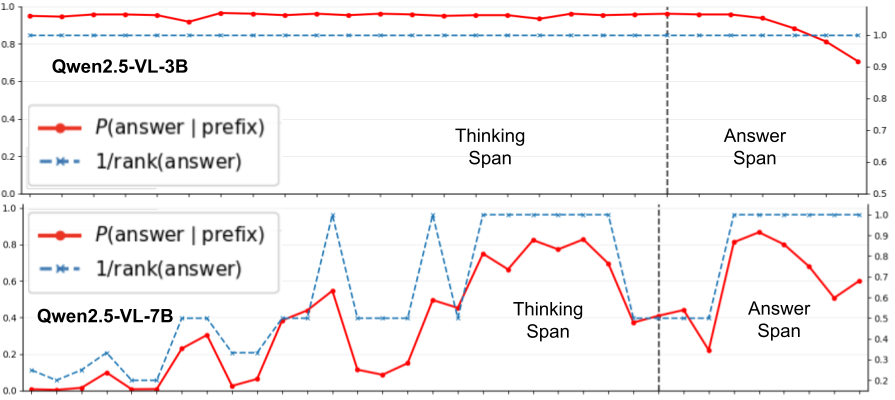
思維鏈(CoT)提示在多模態大型語言模型(MLLM)中的有效性仍不明確:在多個視覺推理基準上,CoT提示相較直接提示常導致效能下降。本文針對三個現代MLLM家族、跨模型規模,在需要逐步視覺證據的資料集上系統性分析CoT行為。分析找出兩個反覆出現的失效模式:過早承諾答案,以及生成理由過程中對視覺token的直接存取受限。我們進一步發現,標準的CoT式監督微調(CoT-SFT)僅能部分緩解這些問題,且常增加對文字先驗的依賴、降低反事實視覺依賴。基於這些發現,我們提出Attentive-CoT(Att-CoT)——一個注意力引導的微調目標,促使CoT軌跡延遲答案承諾,同時維持對視覺token的持續存取。Att-CoT無需架構修改即可嵌入任何CoT-SFT訓練。在三個視覺推理基準與六個MLLM上的實驗顯示,Att-CoT較標準微調提升CoT效能。
原始摘要(英文)
The effectiveness of Chain-of-Thought (CoT) prompting in Multimodal Large Language Models (MLLMs) remains uncertain: across several visual reasoning benchmarks, CoT prompting often degrades performance compared to direct prompting. In this paper, we provide a systematic analysis of CoT behavior in three modern MLLM families across model scales on datasets requiring step-wise visual evidence. Our analysis identifies two recurring failure modes: premature answer commitment and limited direct visual-token access during rationale generation. We further find that standard CoT-style Supervised Fine-Tuning (CoT-SFT) can mitigate these issues only partially, while often increasing reliance on textual priors and reducing counterfactual visual dependence. Motivated by these findings, we propose Attentive-CoT (Att-CoT), an attention-guided fine-tuning objective that encourages CoT trajectories to delay answer commitment while maintaining sustained visual-token access. Att-CoT can be plugged into any CoT-SFT training run without architectural changes. Experiments on three visual reasoning benchmarks across six MLLMs show that Att-CoT enhances CoT performance over standard fine-tuning.
本文貢獻
Fine-tuning only a few attention maps, not weights, of multimodal LLMs improves chain-of-thought reasoning. Attention-guided updates steer where the model looks while keeping its knowledge intact, lifting ChartQA and CoT benchmarks at a fraction of full fine-tuning cost.
BibTeX
@misc{sinha2026attention,
  title         = {Attention-guided Fine-tuning of Multimodal Large Language Models Improves Chain-of-Thought Reasoning},
  author        = {Sanchit Sinha and Guangzhi Xiong and Bohan Liu and Zhenghao He and Aidong Zhang},
  year          = {2026},
  eprint        = {arXiv:2606.01558},
  howpublished  = {arXiv:2606.01558}
}