Attention-guided Fine-tuning of Multimodal Large Language Models Improves Chain-of-Thought Reasoning
Sanchit Sinha, Guangzhi Xiong, 刘博涵 (Bohan Liu), Zhenghao He, Aidong Zhang
概要
この概要は英語原文から自動翻訳されています。
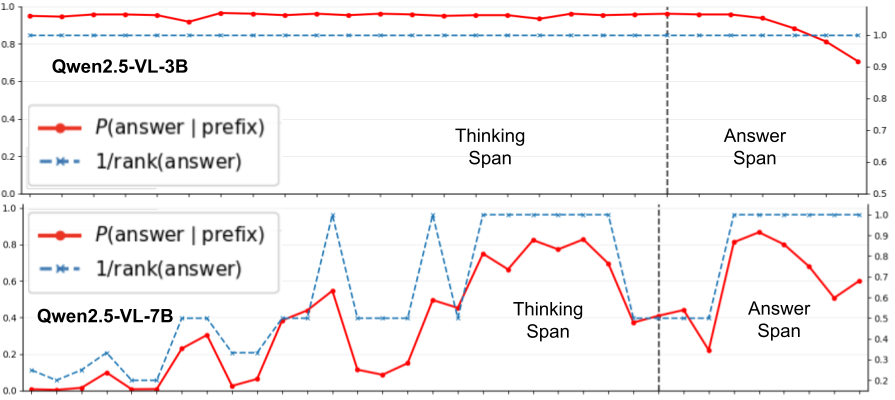
マルチモーダル大規模言語モデル(MLLM)における推論連鎖(CoT)プロンプティングの有効性は不確かなままある:複数の視覚推論ベンチマークにおいて、CoTプロンプティングはしばしば直接プロンプティングと比較して性能を低下させる。本稿では、段階的な視覚的証拠を要するデータセット上で、3つの最新MLLMファミリーにわたりモデルスケールを横断してCoTの挙動を体系的に分析する。分析の結果、2つの繰り返し現れる故障モードを特定した:解答への早期コミットと、根拠生成中の直接的な視覚トークンアクセスの制限である。さらに、標準的なCoTスタイルの教師ありファインチューニング(CoT-SFT)はこれらの問題を部分的にしか緩和できず、しばしばテキスト的事前知識への依存を増大させ、反実仮想的な視覚依存を低下させることを見出した。これらの知見に動機づけられ、注意ガイド付きファインチューニング目的Attentive-CoT(Att-CoT)を提案する。これは、持続的な視覚トークンアクセスを維持しつつ、CoT軌跡が解答コミットを遅らせるよう促す。Att-CoTはアーキテクチャ変更なしに任意のCoT-SFT訓練に組み込める。3つの視覚推論ベンチマークと6つのMLLMでの実験により、Att-CoTが標準ファインチューニングを上回るCoT性能をもたらすことを示す。
原文(英語)
The effectiveness of Chain-of-Thought (CoT) prompting in Multimodal Large Language Models (MLLMs) remains uncertain: across several visual reasoning benchmarks, CoT prompting often degrades performance compared to direct prompting. In this paper, we provide a systematic analysis of CoT behavior in three modern MLLM families across model scales on datasets requiring step-wise visual evidence. Our analysis identifies two recurring failure modes: premature answer commitment and limited direct visual-token access during rationale generation. We further find that standard CoT-style Supervised Fine-Tuning (CoT-SFT) can mitigate these issues only partially, while often increasing reliance on textual priors and reducing counterfactual visual dependence. Motivated by these findings, we propose Attentive-CoT (Att-CoT), an attention-guided fine-tuning objective that encourages CoT trajectories to delay answer commitment while maintaining sustained visual-token access. Att-CoT can be plugged into any CoT-SFT training run without architectural changes. Experiments on three visual reasoning benchmarks across six MLLMs show that Att-CoT enhances CoT performance over standard fine-tuning.
本論文の貢献
マルチモーダルLLMの重みではなく一部の注意マップのみをファインチューニングすることで、推論連鎖(CoT)が改善します。注意ガイド付き更新はモデルの知識を保ちつつ「どこを見るか」を制御し、フルファインチューニングのわずかなコストでChartQAやCoTベンチマークを向上させます。
BibTeX
@misc{sinha2026attention,
  title         = {Attention-guided Fine-tuning of Multimodal Large Language Models Improves Chain-of-Thought Reasoning},
  author        = {Sanchit Sinha and Guangzhi Xiong and Bohan Liu and Zhenghao He and Aidong Zhang},
  year          = {2026},
  eprint        = {arXiv:2606.01558},
  howpublished  = {arXiv:2606.01558}
}