Attention-guided Fine-tuning of Multimodal Large Language Models Improves Chain-of-Thought Reasoning
Sanchit Sinha, Guangzhi Xiong, 刘博涵 (Bohan Liu), Zhenghao He, Aidong Zhang
초록
이 초록은 영어 원문에서 자동 번역되었습니다.
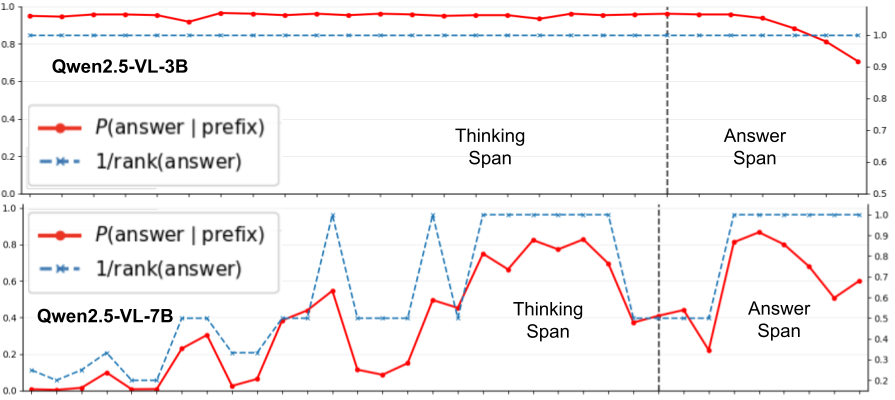
멀티모달 대규모 언어 모델(MLLM)에서 사고연쇄(CoT) 프롬프팅의 효과성은 여전히 불확실하다: 여러 시각 추론 벤치마크에서 CoT 프롬프팅은 직접 프롬프팅에 비해 성능을 저하시키는 경우가 많다. 본 논문은 단계적 시각 증거를 요구하는 데이터셋에서 세 개의 최신 MLLM 계열과 모델 규모에 걸쳐 CoT 동작을 체계적으로 분석한다. 분석을 통해 반복되는 두 가지 실패 모드를 식별했다: 조기 답변 확정과 근거 생성 중 직접적 시각 토큰 접근의 제한이다. 나아가 표준 CoT 방식의 지도 미세조정(CoT-SFT)은 이러한 문제를 부분적으로만 완화하며, 텍스트 사전지식에 대한 의존을 높이고 반사실적 시각 의존성을 낮추는 경우가 많음을 발견했다. 이러한 발견에 동기하여, CoT 궤적이 답변 확정을 지연시키면서 시각 토큰에 대한 지속적 접근을 유지하도록 유도하는 어텐션 유도 미세조정 목표 Attentive-CoT(Att-CoT)를 제안한다. Att-CoT는 아키텍처 변경 없이 모든 CoT-SFT 학습에 플러그인될 수 있다. 세 개의 시각 추론 벤치마크와 여섯 개 MLLM에 대한 실험에서 Att-CoT가 표준 미세조정 대비 CoT 성능을 향상시킴을 보인다.
원문 초록 (영어)
The effectiveness of Chain-of-Thought (CoT) prompting in Multimodal Large Language Models (MLLMs) remains uncertain: across several visual reasoning benchmarks, CoT prompting often degrades performance compared to direct prompting. In this paper, we provide a systematic analysis of CoT behavior in three modern MLLM families across model scales on datasets requiring step-wise visual evidence. Our analysis identifies two recurring failure modes: premature answer commitment and limited direct visual-token access during rationale generation. We further find that standard CoT-style Supervised Fine-Tuning (CoT-SFT) can mitigate these issues only partially, while often increasing reliance on textual priors and reducing counterfactual visual dependence. Motivated by these findings, we propose Attentive-CoT (Att-CoT), an attention-guided fine-tuning objective that encourages CoT trajectories to delay answer commitment while maintaining sustained visual-token access. Att-CoT can be plugged into any CoT-SFT training run without architectural changes. Experiments on three visual reasoning benchmarks across six MLLMs show that Att-CoT enhances CoT performance over standard fine-tuning.
이 논문의 기여
멀티모달 LLM의 가중치가 아닌 일부 어텐션 맵만 미세조정해도 사고연쇄(CoT) 추론이 향상됩니다. 어텐션 유도 업데이트는 모델 지식을 보존하며 '보는 곳'을 조절해, 전체 미세조정 비용의 일부로 ChartQA와 CoT 벤치마크를 끌어올립니다.
BibTeX
@misc{sinha2026attention,
  title         = {Attention-guided Fine-tuning of Multimodal Large Language Models Improves Chain-of-Thought Reasoning},
  author        = {Sanchit Sinha and Guangzhi Xiong and Bohan Liu and Zhenghao He and Aidong Zhang},
  year          = {2026},
  eprint        = {arXiv:2606.01558},
  howpublished  = {arXiv:2606.01558}
}