Triggering Chain-of-Thought via Latent Feature Interventions in Large Language Models
Zhenghao He, Guangzhi Xiong, 刘博涵 (Bohan Liu), Sanchit Sinha, Aidong Zhang
초록
이 초록은 영어 원문에서 자동 번역되었습니다.
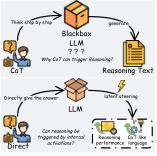
사고연쇄(CoT) 프롬프팅은 대규모 언어 모델(LLM)의 추론 성능을 종종 향상시키지만, 이러한 동작을 유발하는 내부 신호는 여전히 잘 이해되지 않는다. 희소 오토인코더(SAE)가 포착한 희소 특징을 활용하여, 우리는 LLM의 내부 표현을 분석하고 개입하는 체계적 프레임워크를 제안하며, 추론 동작과 연관되고 표적 개입을 통해 인과적으로 검증 가능한 소수의 잠재 특징을 식별한다. 여러 모델 계열과 추론 벤치마크에서, 추론 관련 잠재 특징 하나 또는 소수를 스티어링하는 것만으로 명시적 CoT 프롬프팅 없이도 실질적으로 추론 동작을 유도할 수 있으며 CoT와 대등한 정확도에 도달함을 보인다. 나아가 식별된 특징이 특정 표현 패턴이나 장황함에 의존하지 않음을 보이고, CoT 프롬프팅 하에서도 성능을 저해하는 억제 실험을 통해 추론에서의 인과적 역할을 확인한다. 이 결과들은 CoT 프롬프팅이 특정 잠재 특징을 활성화하여 추론을 유발하며, 이 특징들에 대한 표적 개입이 명시적 CoT 프롬프팅 없이 효율적인 추론 동작을 이끌어내는 대체 경로를 제공함을 시사한다. 코드는 https://github.com/Zhenghao-He/LatentCoT에서 이용 가능하다.
원문 초록 (영어)
Chain-of-Thought (CoT) prompting often improves the reasoning performance of large language models (LLMs), but the internal signal that triggers this behavior remains poorly understood. Leveraging the sparse features captured by Sparse Autoencoders (SAEs), we propose a systematic framework to analyze and intervene on the internal representations of LLMs, identifying a small set of latent features that are linked to reasoning behavior and can be causally tested through targeted intervention. Across multiple model families and reasoning benchmarks, we show that steering one or a small number of reasoning-related latent features can substantially induce reasoning behavior without explicit CoT prompting, achieving accuracy comparable to CoT. We further show that the identified features are not tied to particular wording patterns or verbosity, and confirm their causal role in reasoning through suppression experiments that impair performance even under CoT prompting. These results suggest that CoT prompting activates specific latent features to trigger reasoning, and that targeted intervention on these features offers an alternative pathway to elicit efficient reasoning behavior without explicit CoT prompting. Code is available at https://github.com/Zhenghao-He/LatentCoT.
이 논문의 기여
사고연쇄가 LLM이 추론하는 유일한 방법은 아닙니다. 어떤 토큰도 생성되기 전에 은닉 상태 안에서 완료되는 잠재 계산 모드를 발견하고, 잠재 계산이 명시적 CoT를 능가하는 조건을 특징짓습니다.
BibTeX
@misc{he2026latent,
  title         = {Triggering Chain-of-Thought via Latent Feature Interventions in Large Language Models},
  author        = {Zhenghao He and Guangzhi Xiong and Bohan Liu and Sanchit Sinha and Aidong Zhang},
  year          = {2026},
  eprint        = {arXiv:2601.08058},
  howpublished  = {arXiv:2601.08058}
}