Triggering Chain-of-Thought via Latent Feature Interventions in Large Language Models
Zhenghao He, Guangzhi Xiong, 刘博涵 (Bohan Liu), Sanchit Sinha, Aidong Zhang
概要
この概要は英語原文から自動翻訳されています。
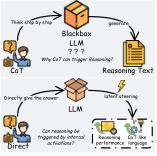
推論連鎖(CoT)プロンプティングは大規模言語モデル(LLM)の推論性能をしばしば向上させるが、この挙動を引き起こす内部信号は依然としてよく理解されていない。スパースオートエンコーダ(SAE)が捉えるスパースな特徴を利用し、LLMの内部表現を分析・介入する体系的フレームワークを提案し、推論挙動に関連し標的介入による因果的検証が可能な少数の潜在特徴を特定する。複数のモデルファミリーと推論ベンチマークにわたり、推論関連の潜在特徴1つまたは少数をステアリングするだけで、明示的なCoTプロンプティングなしに推論挙動を実質的に誘導でき、CoTと同等の精度を達成できることを示す。さらに、特定された特徴が特定の表現パターンや冗長性に依存しないことを示し、CoTプロンプティング下でも性能を損なう抑制実験により推論における因果的役割を確認する。これらの結果は、CoTプロンプティングが特定の潜在特徴を活性化して推論を引き起こすこと、そしてこれらの特徴への標的介入が、明示的なCoTプロンプティングなしに効率的な推論挙動を引き出す代替経路を提供することを示唆する。コードはhttps://github.com/Zhenghao-He/LatentCoTで入手可能である。
原文(英語)
Chain-of-Thought (CoT) prompting often improves the reasoning performance of large language models (LLMs), but the internal signal that triggers this behavior remains poorly understood. Leveraging the sparse features captured by Sparse Autoencoders (SAEs), we propose a systematic framework to analyze and intervene on the internal representations of LLMs, identifying a small set of latent features that are linked to reasoning behavior and can be causally tested through targeted intervention. Across multiple model families and reasoning benchmarks, we show that steering one or a small number of reasoning-related latent features can substantially induce reasoning behavior without explicit CoT prompting, achieving accuracy comparable to CoT. We further show that the identified features are not tied to particular wording patterns or verbosity, and confirm their causal role in reasoning through suppression experiments that impair performance even under CoT prompting. These results suggest that CoT prompting activates specific latent features to trigger reasoning, and that targeted intervention on these features offers an alternative pathway to elicit efficient reasoning behavior without explicit CoT prompting. Code is available at https://github.com/Zhenghao-He/LatentCoT.
本論文の貢献
推論連鎖はLLMの唯一の推論方法ではありません。トークンを生成する前に隠れ状態の中で完結する潜在的計算モードを発見し、潜在計算が明示的CoTを上回る条件を特徴付けます。
BibTeX
@misc{he2026latent,
  title         = {Triggering Chain-of-Thought via Latent Feature Interventions in Large Language Models},
  author        = {Zhenghao He and Guangzhi Xiong and Bohan Liu and Sanchit Sinha and Aidong Zhang},
  year          = {2026},
  eprint        = {arXiv:2601.08058},
  howpublished  = {arXiv:2601.08058}
}